Short answer: A server-side tracking project is not complete when a server starts receiving events. It is complete when you can prove the right events are collected, duplicates are controlled, consent behavior is defined, failures are observable, and rollback is possible.
Define the measurement problem first
Write down the failure you are trying to fix before choosing infrastructure.
- Purchase or Lead events are missing.
- Conversions are duplicated.
- Meta, Google Ads, analytics, and store orders disagree in ways you cannot explain.
- Click identifiers disappear during checkout.
- Several apps or scripts compete to send the same event.
- The team cannot tell whether a destination accepted or rejected an event.
The implementation controls you need
- Choose the business source of truth. For ecommerce, the order system is usually the baseline for real orders.
- Create an event inventory. Document who owns PageView, AddToCart, Checkout, Purchase, Lead, and Refund.
- Define event identity. Specify how browser and server copies share one logical event ID and how retries behave.
- Document consent. Define what happens before consent, after consent, when denied, and when state changes.
- Preserve accurate identifiers. Keep only the permitted order, event, session, click, browser, and customer identifiers your architecture genuinely needs.
Pre-launch QA checklist
- Validate event name, timestamp, currency, value, items, order ID, event ID, and applicable consent state.
- Test browser/server deduplication using one real or controlled test order.
- Test payment redirects, mobile checkout, reloads, repeated webhooks, destination API failures, invalid credentials, timeouts, denied consent, and malformed values.
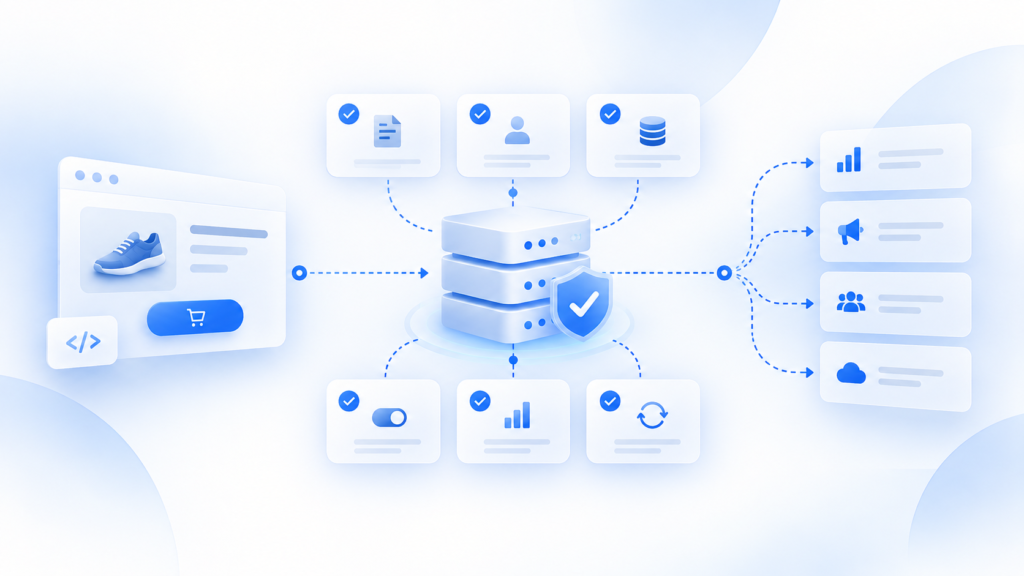
- Add observability for received, rejected, routed, delivered, retried, and deduplicated events.
- Document a kill switch and rollback path before production.
- Launch gradually: preview/test, limited controlled traffic, validate business-critical events, then expand.
- Reconcile store orders, raw conversion events, attributed conversions, and analytics reporting after launch.
Classify discrepancies instead of guessing
- Missing event — the order exists, event is absent.
- Duplicate event — one order produces several logical events.
- Value mismatch — event exists but revenue/currency is wrong.
- Identity loss — event arrives without expected permitted identifiers.
- Attribution difference — raw event exists but the platform assigns credit differently.
Where KePixel fits
KePixel’s current architecture direction includes canonical event contracts, stable event identity, consent-aware identifiers, bounded retries, health/preview, and explicit activation/rollback gates.
Product Truth boundary: source and destination availability varies by current release state. WordPress/WooCommerce customer runtime is still under active implementation.
Key takeaway
Do not call a server-side rollout successful until the event path is explainable, observable, reversible, and verified against real business outcomes.