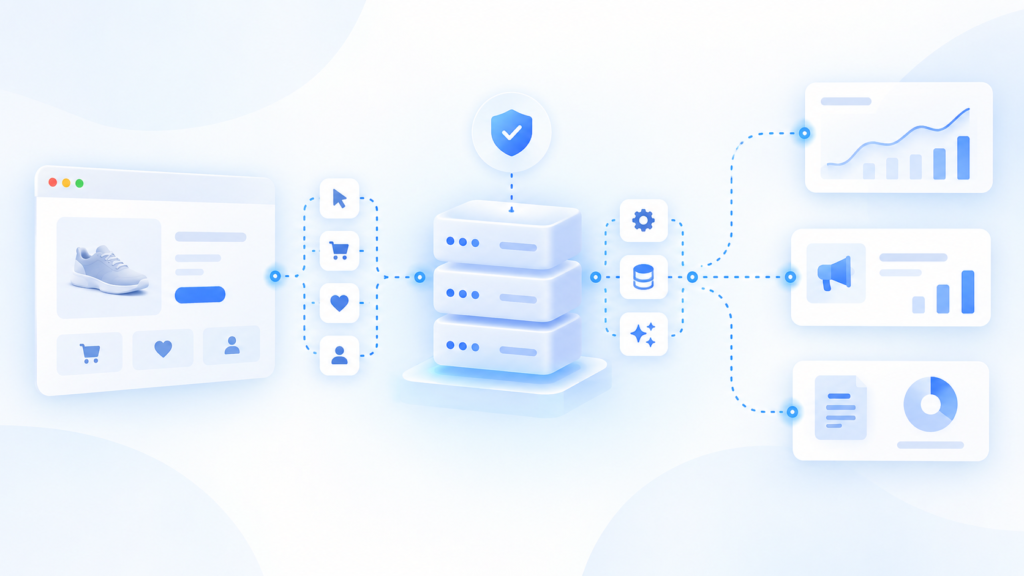
Server-side tracking changes where ecommerce event data is processed before it reaches analytics and advertising platforms.
Server-side tracking is a measurement architecture where events are sent to a server-controlled layer that can receive, validate, process and forward data to approved destinations instead of relying only on the shopper's browser to communicate directly with every vendor. It does not eliminate the browser completely in every setup; rather, it adds a server-side processing path that gives the business more control over how event data is handled.
How server-side tracking moves ecommerce events
A typical ecommerce journey starts with a business event: a product view, add-to-cart, checkout step or completed purchase. In a browser-only setup, the page or app often sends measurement requests directly to analytics and advertising vendors.
With a server-side architecture, the website or app can send the event to a server-controlled endpoint first. That layer receives the request, interprets the event and prepares vendor-specific requests for the destinations that should receive it.
Event collection
The starting point is still the customer's action. A browser, app, backend or another verified source creates the event and passes the relevant data into the tracking flow.
Server processing
The server layer can validate fields, normalize values, apply processing rules and decide which data should be forwarded. Google describes its server container as an intermediary endpoint where incoming data can be screened, validated and modified before it is sent onward.
Event delivery
After processing, the server sends the appropriate request to each configured destination. One business event may therefore be collected once, processed centrally and then delivered in the format required by different analytics or advertising systems.
What changes when tracking moves beyond the browser
The biggest change is not simply that “the server tracks instead of the browser.” The architecture introduces a controlled processing layer between the original event and external platforms.
That can reduce the number of direct vendor requests made from the browser, depending on the implementation. It also gives teams a place to validate event structure and control what data is forwarded.
Data control
A server-side layer can enforce consistent event rules before delivery. That is useful when different browsers, devices or implementation paths produce inconsistent event data.
Browser limitations
Browser restrictions, blocked scripts and page-level implementation problems can affect client-side measurement. A server-side path can reduce dependence on some browser-side processing, but it cannot recreate an event that was never generated or captured at the source.
First-party event flow
When implemented in a first-party context, the website communicates with infrastructure controlled by the business before data is forwarded to external endpoints. The exact privacy and compliance outcome still depends on the implementation, consent requirements and the data being processed.
Where ecommerce stores can benefit from server-side tracking
Ecommerce teams usually care less about the architecture itself than about whether critical conversion events reach the systems used for measurement and advertising.
Server-side tracking can be useful when a business needs a more controlled path for purchase and conversion data, especially when browser-only measurement has become difficult to maintain or validate.
Missing event signals
A server-side setup may reduce certain losses associated with browser-only delivery, but “server-side” is not a guarantee that every missing conversion will suddenly appear. Source events, identifiers, payload quality and destination acceptance still matter.
Event quality
A controlled processing layer creates an opportunity to validate event names, values, currencies and identifiers before events are sent. Better control does not automatically mean the data is correct; the rules still need to be implemented and monitored properly.
Multiple advertising destinations
When the same business event must be delivered to more than one approved destination, centralized processing can reduce duplicated logic across the browser. The exact destinations available in KePixel must always be checked against the current support matrix before publication.
What server-side tracking does not fix
Server-side tracking is measurement infrastructure, not a universal advertising fix.
It cannot repair a weak offer, poor creative, bad campaign targeting or a checkout experience that reduces conversion rate. It also does not make attribution platforms agree automatically. Different systems can use different attribution rules, lookback windows and reporting logic even when they receive high-quality conversion events.
It also cannot correct a business event that is wrong at the source. If the store fires the wrong purchase value, sends the event twice or never creates the event at all, the server layer needs explicit logic and validation to detect or handle that problem.
This distinction matters because a team should diagnose the failure before assuming that “moving server-side” is the answer.
How to know whether your tracking setup needs deeper diagnostics
Start with the data that matters most: completed orders and the conversion events that should represent them.
Compare your source-of-truth orders with the purchase events visible across your tracking paths and destination platforms. Look for missing purchases, duplicates, inconsistent values, mismatched currencies, browser/server discrepancies and events rejected or never received by the destination.
If the numbers do not reconcile, the next step is not automatically a new tool. The next step is to identify where the event path breaks.
Related guides
Frequently Asked Questions
How does server-side tracking move an ecommerce event from the store to an ad platform?
A verified source creates the event; a controlled server layer validates/processes it, then sends it to a verified destination.
What changes when tracking is processed on a server instead of relying only on the browser?
The business gains centralized validation, normalization, deduplication and delivery control, while still needing a valid source event.
Which ecommerce events are commonly handled through a server-side tracking setup?
Critical conversion/customer events can be handled, but the exact event list must be verified per source/destination implementation.
Can server-side tracking reduce data loss caused by browser limitations?
It can reduce browser-only dependency and some signal loss, but cannot guarantee recovery of every missing conversion.
What problems should you not expect server-side tracking to solve by itself?
It does not fix weak campaigns, creative, targeting, checkout friction or attribution-model differences by itself.